Purpose-Built Facilities
Data centers store data.
AI factories manufacture intelligence.
We size power, cooling and the network from the rack outward, then build the facility around them.
AI factories
Every design decision optimizes for token production.
An AI factory turns power into tokens. Three things limit how many it produces: how much power reaches the racks, how much heat leaves them, and how fast the GPUs talk to each other. We design for all three.

Cooled at the chip. Closed loop, no water lost.
01
-
03
Our facilities are designed for direct-to-chip liquid cooling on a sealed loop, so the coolant circulates and is not consumed. Network racks and residual heat are air-cooled. At our Canadian sites, cold outside air does much of the heat rejection for most of the year, which brings annualized PUE well below the 1.41 design point.

Thousands of GPUs. One fabric.
02
-
03
InfiniBand NDR or RoCE connects every GPU in a cluster, so a training run can span racks and pods. Every site is screened for two diverse fibre paths before we commit to it.

Built to Tier III. Serviced while it runs.
03
-
03
Facilities are designed to Tier III intent, so each power and cooling path can be serviced while the load keeps running. UPS carries the transfer to on-site backup generation in a utility event. Physical security includes biometric access and 24/7 monitoring.
NVIDIA
A member of the NVIDIA Partner Network since 2023.
Infinite Compute is a Cloud Service Provider in the NVIDIA Partner Network. We design our facilities to NVIDIA reference architectures for NVIDIA HGX and GB300 NVL72 systems.


Built for What's Next
Built with headroom for every generation of AI hardware to come.

Power headroom.
A GB300 NVL72 rack draws about 140 kW. Cabinets are designed for up to 200 kW, which leaves room for the next generation.
Cooling capacity.
Liquid loops for GPU racks and air for network racks in the same hall, so different hardware generations run side by side.
Network scalability.
One fabric design covers every cluster size. It scales from 8 GPUs to more than 10,000.
Orchestration
SLURM, Kubernetes or bare metal. Your operational layer stays the same as the hardware underneath changes.
Compliance

SOC2 Type II
SOC 2 Type II certified, covering security, availability, and confidentiality controls. Report available to customers on request, and to prospective customers under NDA.

ISO27001
Certification in progress, covering our information security management system across data center operations, cloud platform, and internal controls.
Hardware
An official NVIDIA partner, building to NVIDIA's validated standards.
Our data centers are designed and built to NVIDIA's validated specifications for DGX™ systems, ensuring every GPU cluster we deploy performs to its full potential across current and future hardware generations.
01.
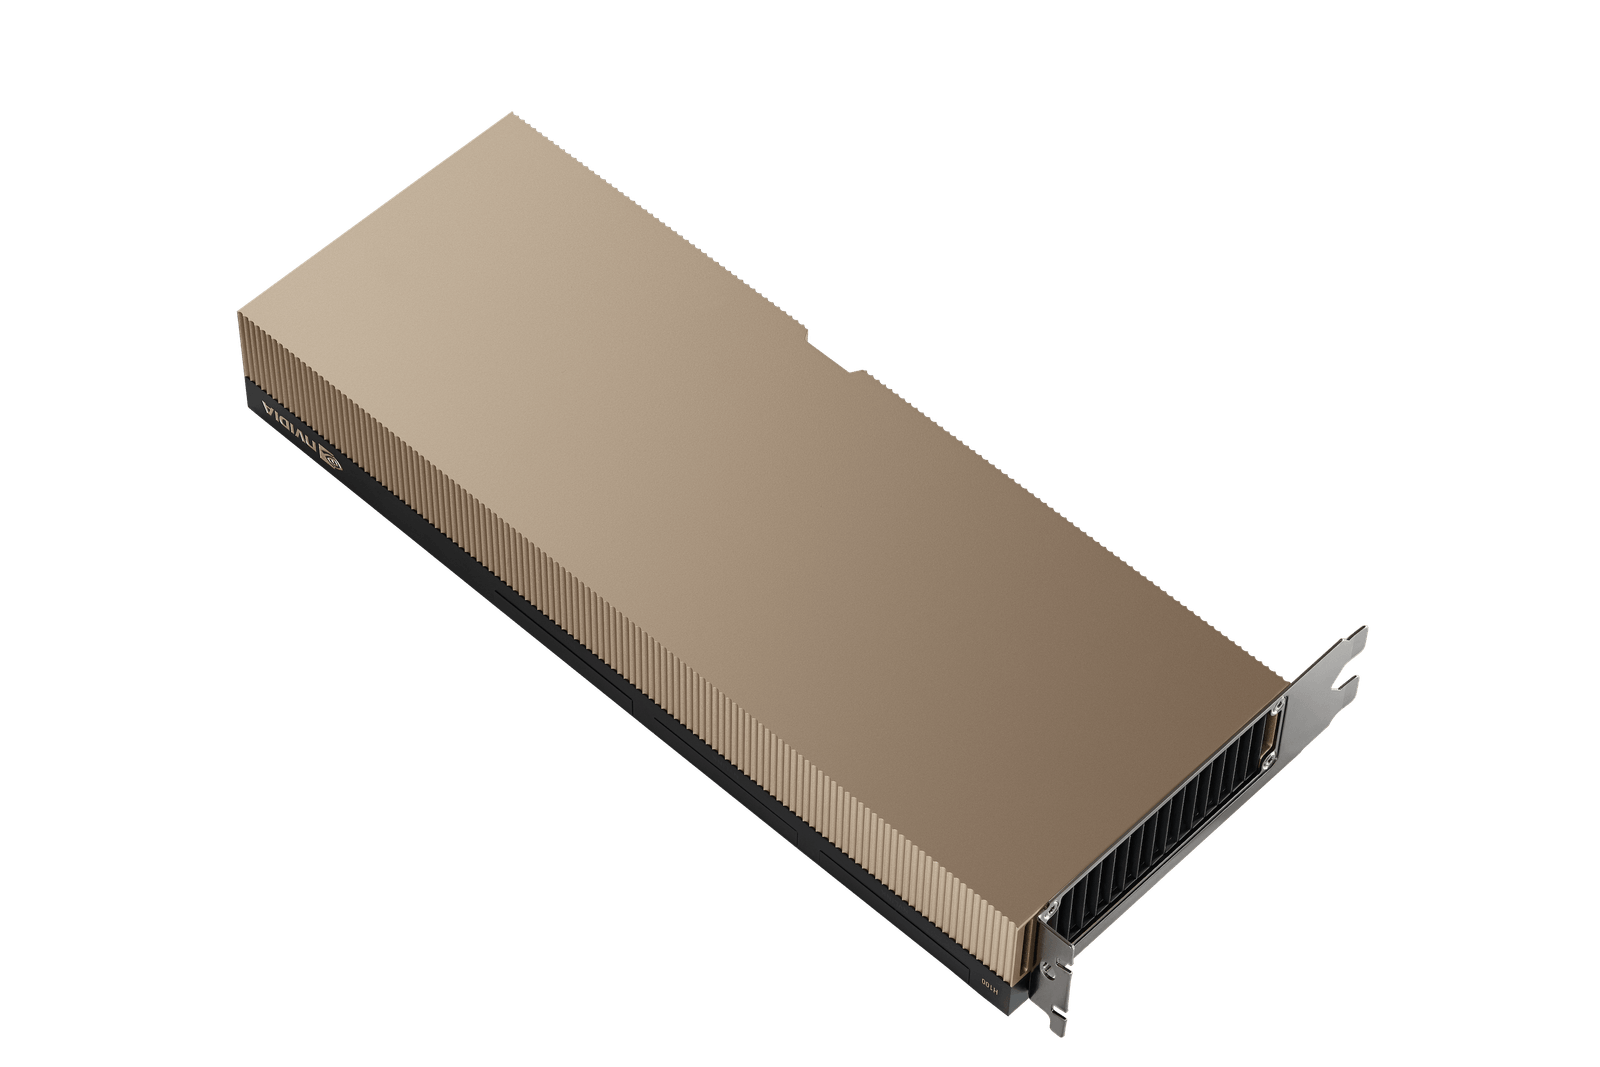
H100 SXM
Architecture
Hopper
Memory
80 GB HBM3
Memory BW
3.35 TB/s
Power
700W TDP
Best for:
60-91% off on-demand pricing, Fault-tolerant workloads only. Best for experimentation
Deployment Options:
Placeholder text for the accordion label goes here. You can easily customize the text through the component settings.
Available:
60-91% off on-demand pricing, Fault-tolerant workloads only. Best for experimentation
H100 SXM
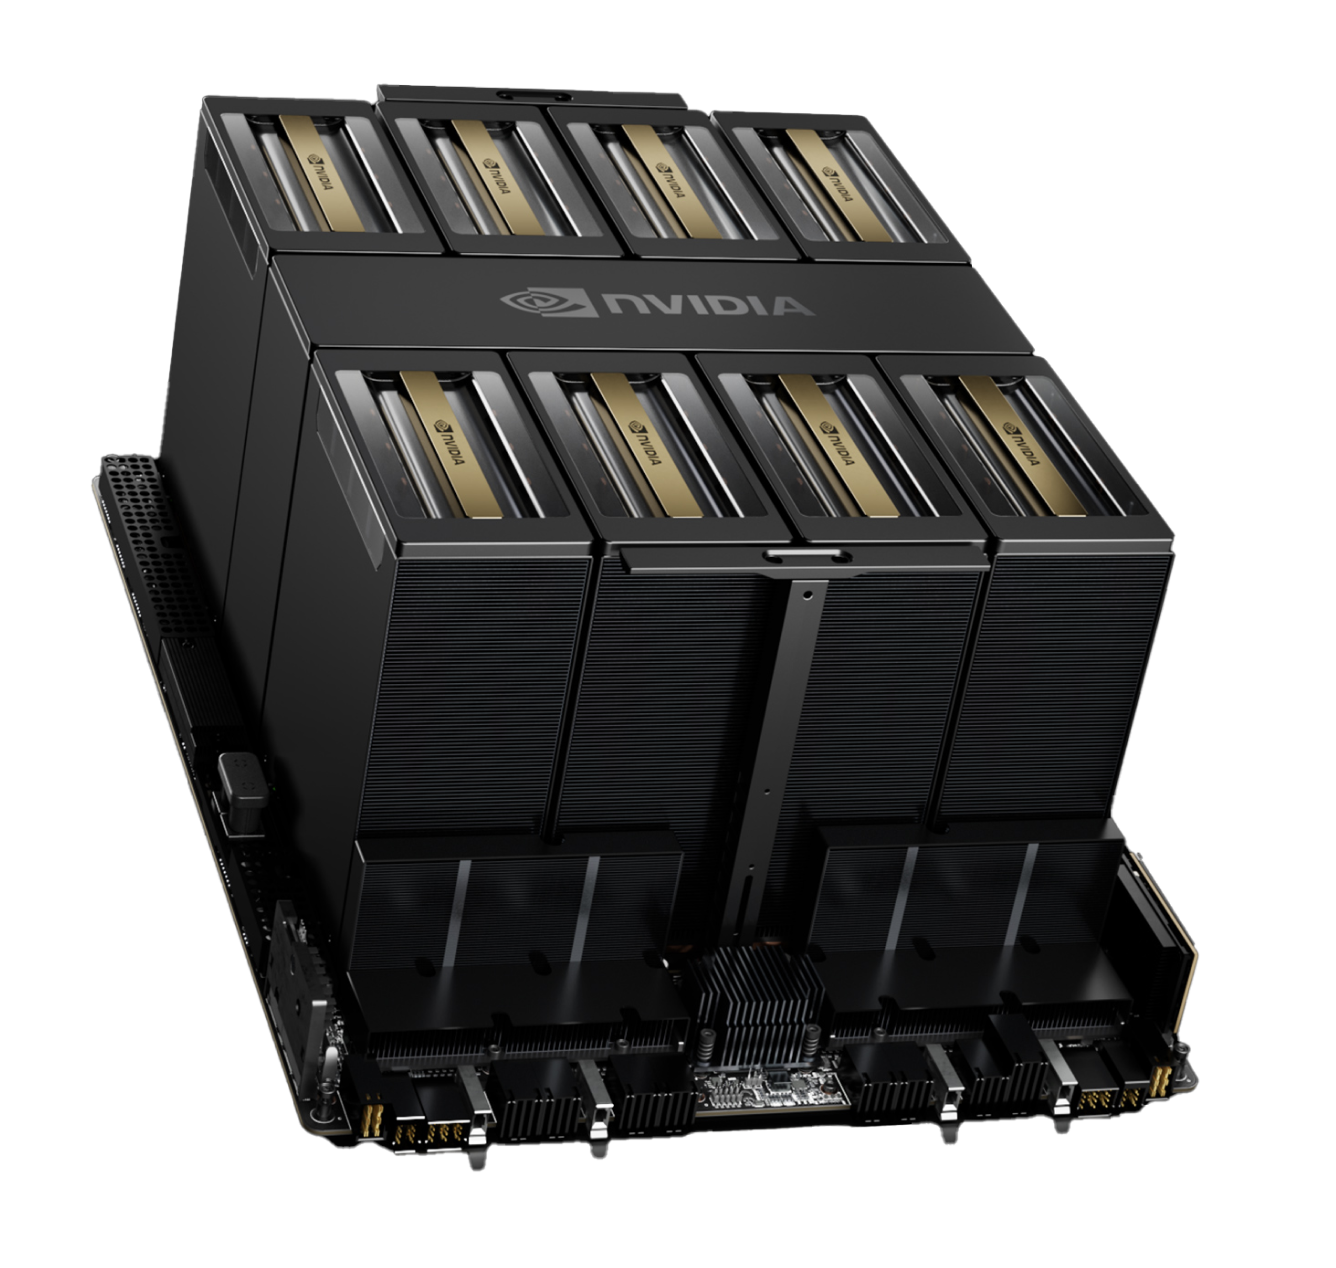
01.
B200 SXM6
Architecture
Blackwell
Memory
192 GB HBM3e
Memory BW
8.0 TB/s
Power
1,000W TDP
Best for:
60-91% off on-demand pricing, Fault-tolerant workloads only. Best for experimentation
Deployment Options:
Placeholder text for the accordion label goes here. You can easily customize the text through the component settings.
Available:
60-91% off on-demand pricing, Fault-tolerant workloads only. Best for experimentation
B200 SXM6
01.
HGX B300
Architecture
Blackwell Ultra
Memory
288 GB HBM3e
Memory BW
8.0 TB/s
Power
1,400W TDP
Best for:
60-91% off on-demand pricing, Fault-tolerant workloads only. Best for experimentation
Deployment Options:
Placeholder text for the accordion label goes here. You can easily customize the text through the component settings.
Available:
60-91% off on-demand pricing, Fault-tolerant workloads only. Best for experimentation
HGX B300
01.
HGX B200
Architecture
Blackwell
Memory
180 GB HBM3e
Memory BW
8.0 TB/s
Power
1,000W TDP
Best for:
60-91% off on-demand pricing, Fault-tolerant workloads only. Best for experimentation
Deployment Options:
Placeholder text for the accordion label goes here. You can easily customize the text through the component settings.
Available:
60-91% off on-demand pricing, Fault-tolerant workloads only. Best for experimentation
HGX B200
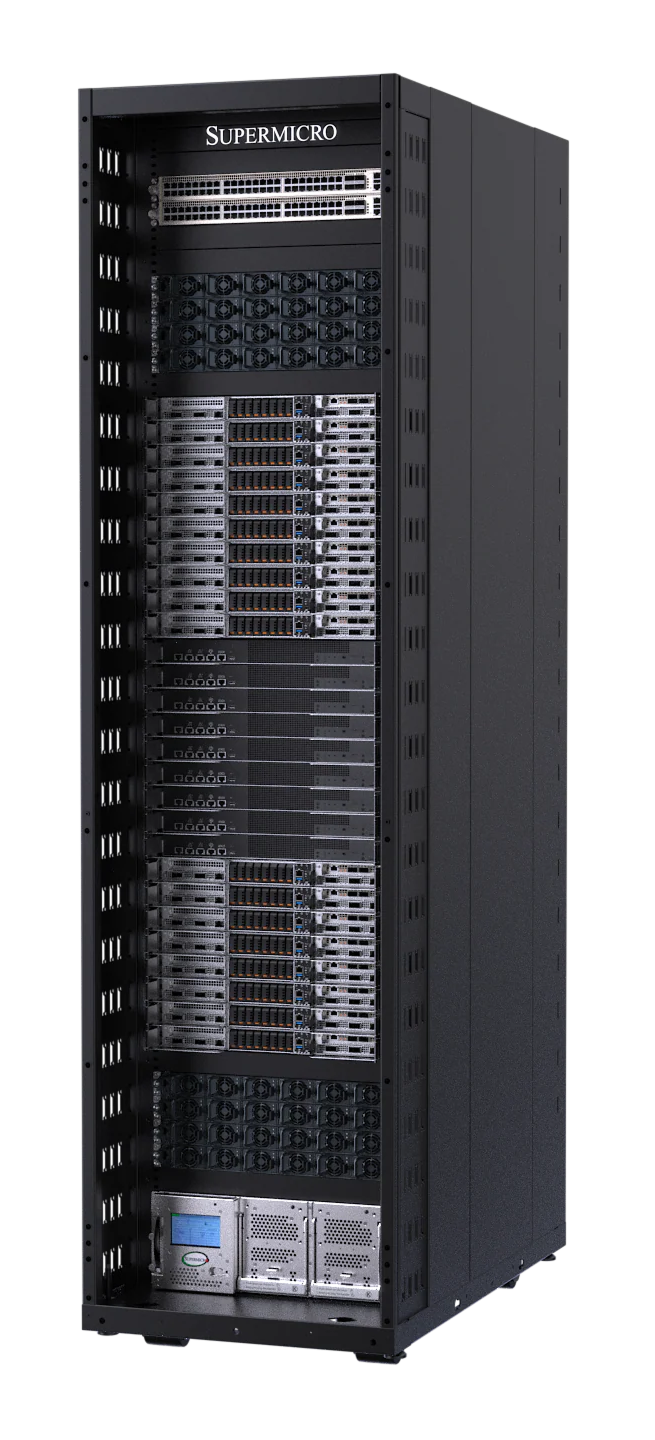
01.
GB200 NVL72
Architecture
Blackwell / Grace
Memory
13.4 TB (72 GPU)
Memory BW
1.4 TB/s per GPU
Power
132 kW rack
Best for:
60-91% off on-demand pricing, Fault-tolerant workloads only. Best for experimentation
Deployment Options:
Placeholder text for the accordion label goes here. You can easily customize the text through the component settings.
Available:
60-91% off on-demand pricing, Fault-tolerant workloads only. Best for experimentation
GB200 NVL72
01.
GB300 NVL72
Architecture
Blackwell Ultra / Grace
Memory
21 TB (72 GPU)
Memory BW
1.8 TB/s per GPU
Power
120 kW rack
Best for:
60-91% off on-demand pricing, Fault-tolerant workloads only. Best for experimentation
Deployment Options:
Placeholder text for the accordion label goes here. You can easily customize the text through the component settings.
Available:
60-91% off on-demand pricing, Fault-tolerant workloads only. Best for experimentation
GB300 NVL72